- Inference and fine-tuning with a stated model and memory profile
- Model training and batch compute with a defined topology
- Rendering, video and graphics workloads with measurable acceptance criteria
GPU cloud India
GPU cloud in India, priced in INR.
Monthly NVIDIA GPU cloud capacity in India with public INR reference pricing. Compare L4, L40S, A100, H100, H200, B200 and RTX PRO 6000.
Commercial unitPer GPU card per month
Public currencyINR
ModelsL4 through B200-class
System detail
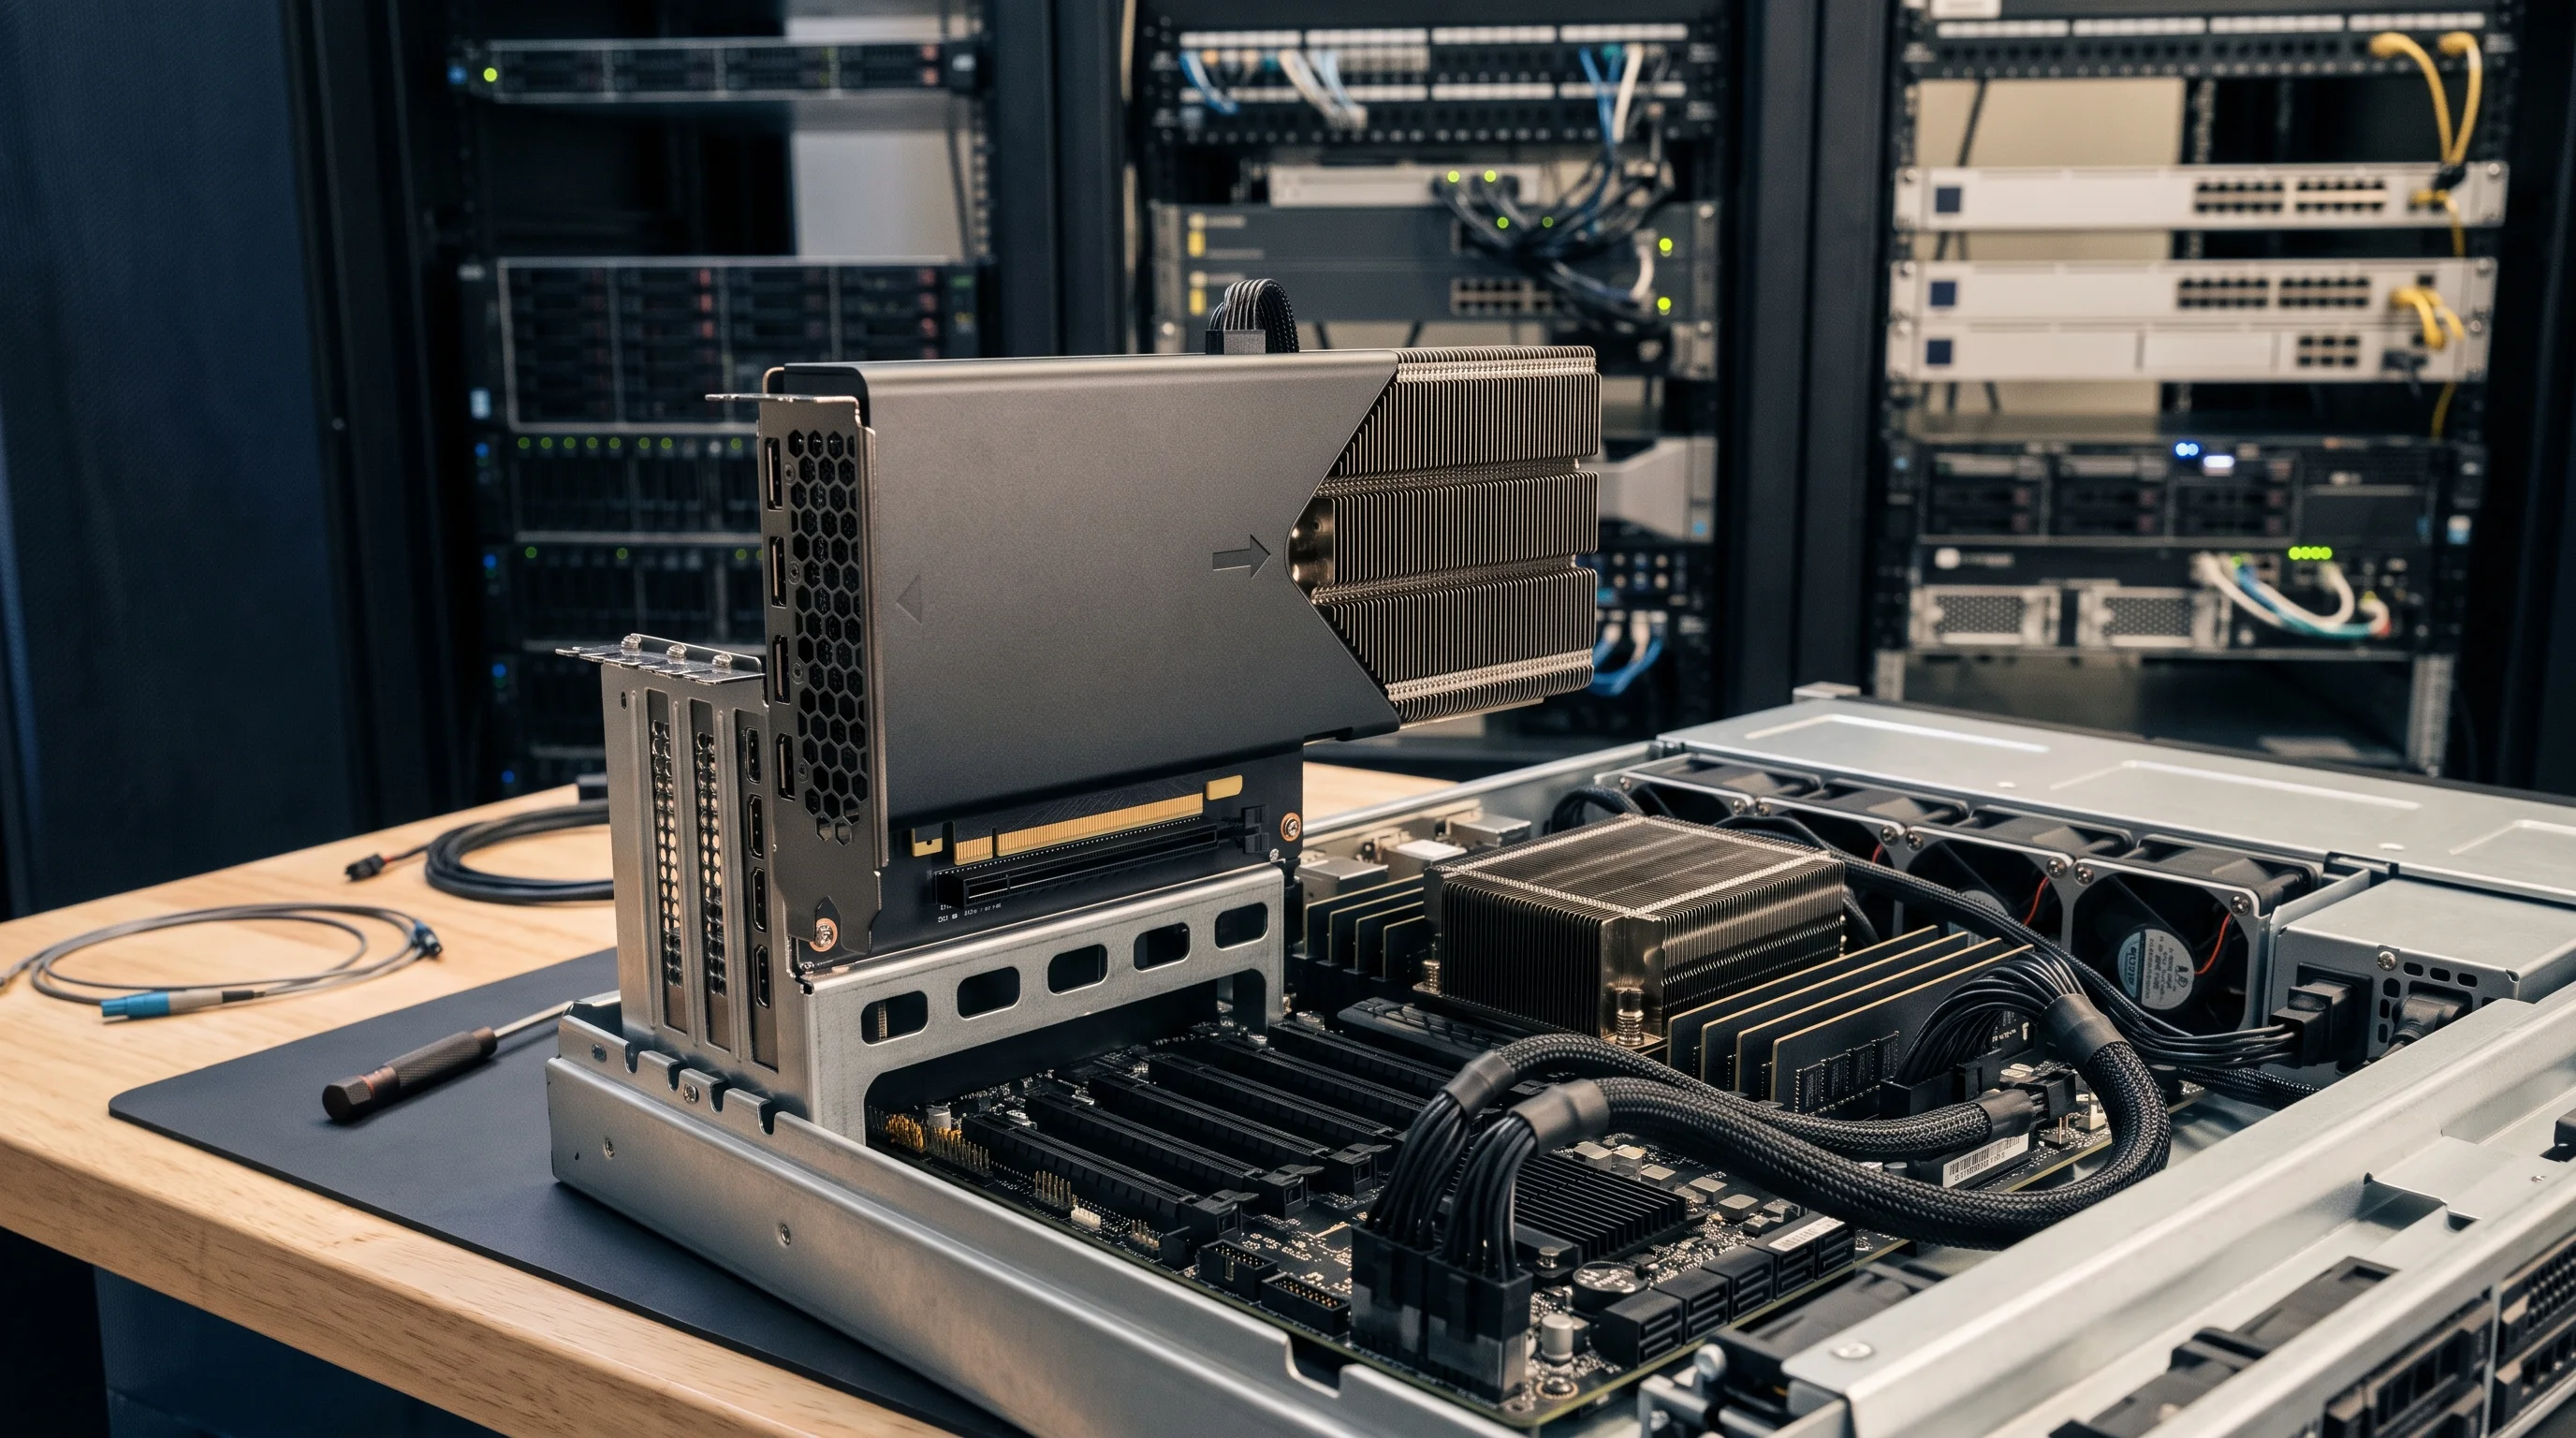
The accelerator is part of a complete system.
GPU memory, card count, form factor, host resources and data movement must fit the actual model or batch workload.
- Accelerator
- Exact GPU, VRAM, card count, form factor and tenancy are stated.
- Host system
- CPU, RAM, local storage and operating environment are confirmed.
- Data path
- Network, storage, transfer and dataset movement are considered.
- Acceptance
- Framework, model and workload checks close the deployment.
Monthly GPU prices in India
Reference pricing in INR.
Compare monthly per-card prices. Request a complete-node quote when host CPU, RAM, storage and topology matter.
OfferINRUnitNext step
A published price does not confirm current stock. Configuration, region, capacity and lead time are confirmed before order.
View the complete price bookWhere it fits.
- A GPU name does not prove workload fit
- A per-card price is not a complete-node price
- Performance claims require an agreed and reproducible test
Common questions.
Is the public price per card or per node?
Per GPU card per month unless the specific row and quote state a complete node and its card count.
Does adding a second GPU combine the available VRAM?
Not automatically. Two cards provide two separate memory pools unless the model, framework and parallelism strategy distribute work across them. The workload must be checked against per-card memory, communication overhead and the selected topology.
Can the GPU server and application server use the same private network?
Yes where the quoted platform, region and network design support it. The quote should state the VPC or private-network boundary, routes, security rules, public access and any cross-network transfer treatment.
Do you offer hourly GPU billing?
This public catalogue is monthly. ZenoCloud does not present an effective hourly comparison as an orderable hourly product.
Can ZenoCloud deploy and operate the workload?
Yes. Deployment and acceptance are one-time services. GPU Infrastructure Care and AI Production Care are separate recurring scopes with named responsibilities and exclusions.